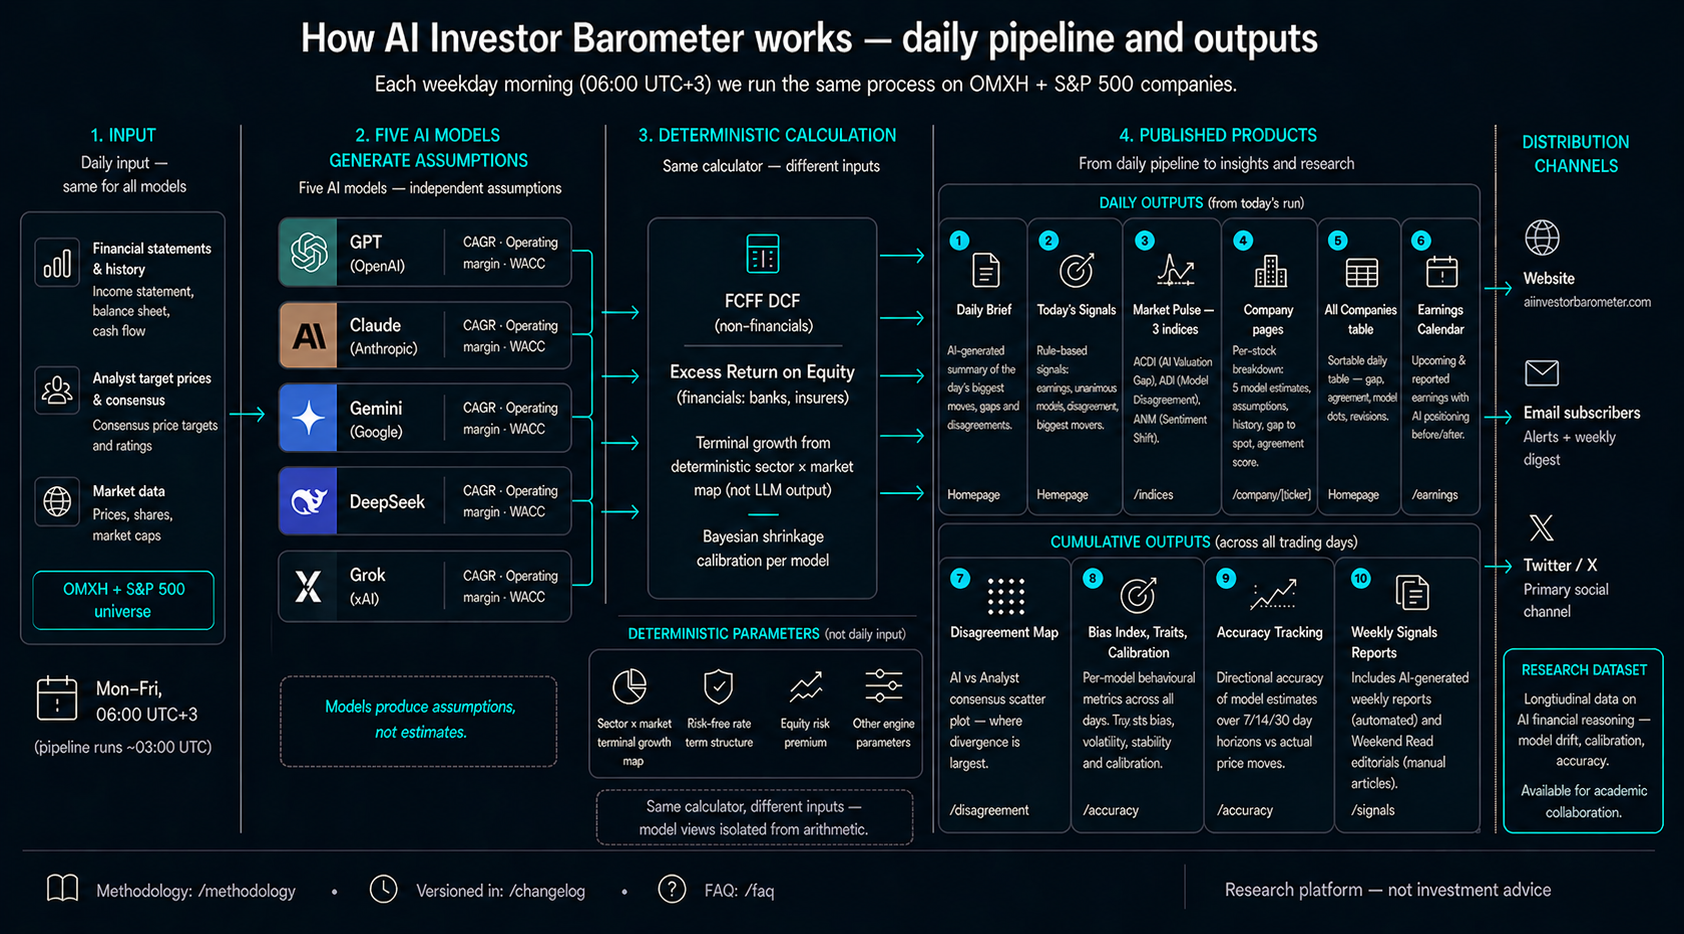
AI Investor Barometer is an experimental comparison tool that uses five different AI models to generate valuation assumptions for listed stocks daily. Each model — GPT, Claude, Gemini, DeepSeek and Grok — independently produces its own estimate from the same company's public data. Results are presented side by side.
Currently tracking 12 Finnish Nasdaq Helsinki stocks and 12 US large-cap companies. The pipeline runs automatically on business days.
The project does not provide investment recommendations or advice. It is an experimental research tool: what do different AI models estimate about the same stocks, and do they differ from each other?
AI is increasingly involved in investment decisions — either directly or indirectly through analysis tools, news aggregations and chatbots. The problem is that a single model appears reliable even when it is systematically over- or under-estimating certain stocks.
When five different models estimate the same company on the same day, you immediately see:
These questions are essential if you want to understand how different AI models differ. This tool makes model-specific comparison visible.
Most AI outputs are black boxes: the model gives a number directly without you knowing how it arrived at it. In this project, the approach is different.
This approach makes model-specific differences transparent: if GPT and Claude arrive at different estimates, it's due to different growth assumptions — not because one "calculated incorrectly".
A growing body of academic research examines whether large language models can reason about financial data. Most studies test a single model on a single task — sentiment classification, earnings prediction, or stock price forecasting. This project takes a different approach: five LLMs run the same valuation task daily, over months, producing a behavioural dataset that captures how model opinions form, drift, and diverge.
The platform generates three types of empirical data that are difficult to obtain elsewhere: temporal consistency (how much a model changes its estimate for the same stock day to day), cross-model disagreement (where models converge and where they don't), and assumption-level transparency (the exact CAGR, margin, and WACC inputs each model produces, not just the final number).
Selected references from the emerging LLM-finance literature:
| Model | Avg Latency | Tokens (in / out) | Cost / Run | Valid % |
|---|---|---|---|---|
| Claudeclaude-sonnet-4-6 | 33.3s | 161.3k / 37.6k | $1.048 | 100% |
| Deepseekdeepseek-v4-flash | 3.8s | 135.4k / 19.5k | $0.058 | 100% |
| Geminigemini-3.5-flash | 8.5s |
Have feedback, a collaboration idea, or a question? We'd love to hear from you.
| 136.9k / 11.1k |
| $0.227 |
| 100% |
| Gptgpt-5.4-mini | 3.0s | 125.5k / 11.7k | $0.431 | 100% |
| Grokgrok-4.3 | 7.5s | 124.0k / 10.3k | $0.351 | 100% |